Research
Understanding how chemistry is genetically encoded
An organism’s genome encodes its ability to sense and manipulate chemistry. This is mostly accomplished through protein biosensors that bind small molecules and enzymes that transform them. We aim to map the relationship between protein sequence and chemical specificity/catalysis via large-scale data generation.
Strategy
Our research is both experimental and computational by nature. Projects often start with a question, such as “how does enzyme sequence govern enantioselectivity?”, and a dataset designed to answer it. Datasets are defined by the protein sequences and chemicals we test, and the phenotypes we measure (EC50, activity, selectivity).
We design and tune genetic circuits that link our desired protein phenotype to gene expression, relying on genetic sensors that activate transcription upon binding specific small molecules. Chemical libraries are read out as cellular fluorescence via RFP expression; protein libraries through growth-based antibiotic selections with massively parallel sequencing, both supported by Sanger’s automation infrastructure. For a sense of scale, our past datasets cover >300,000 protein variants and >4,000 small molecules. We then calibrate these measurements against biophysical parameters (Kd, KM) via in vitro assays, and sometimes solve protein structures to connect genotype–phenotype data to mechanism.
Another core strength of our research program is international collaboration, both for computational protein design and scaling data generation. We work closely with a large team of ML engineers on a project called evedesign, which aims to make multi-objective, model-agnostic AI protein design open-source and accessible. We also collaborate with automation and metrology labs, including the National Institute of Standards and Technology (NIST) and the National Physical Laboratory (NPL) to ensure our data is “AI-ready”, in that it is quantitative, biophysically meaningful, uncertainty-aware, and reproducible.
Completing an atlas of prokaryotic transcription factors
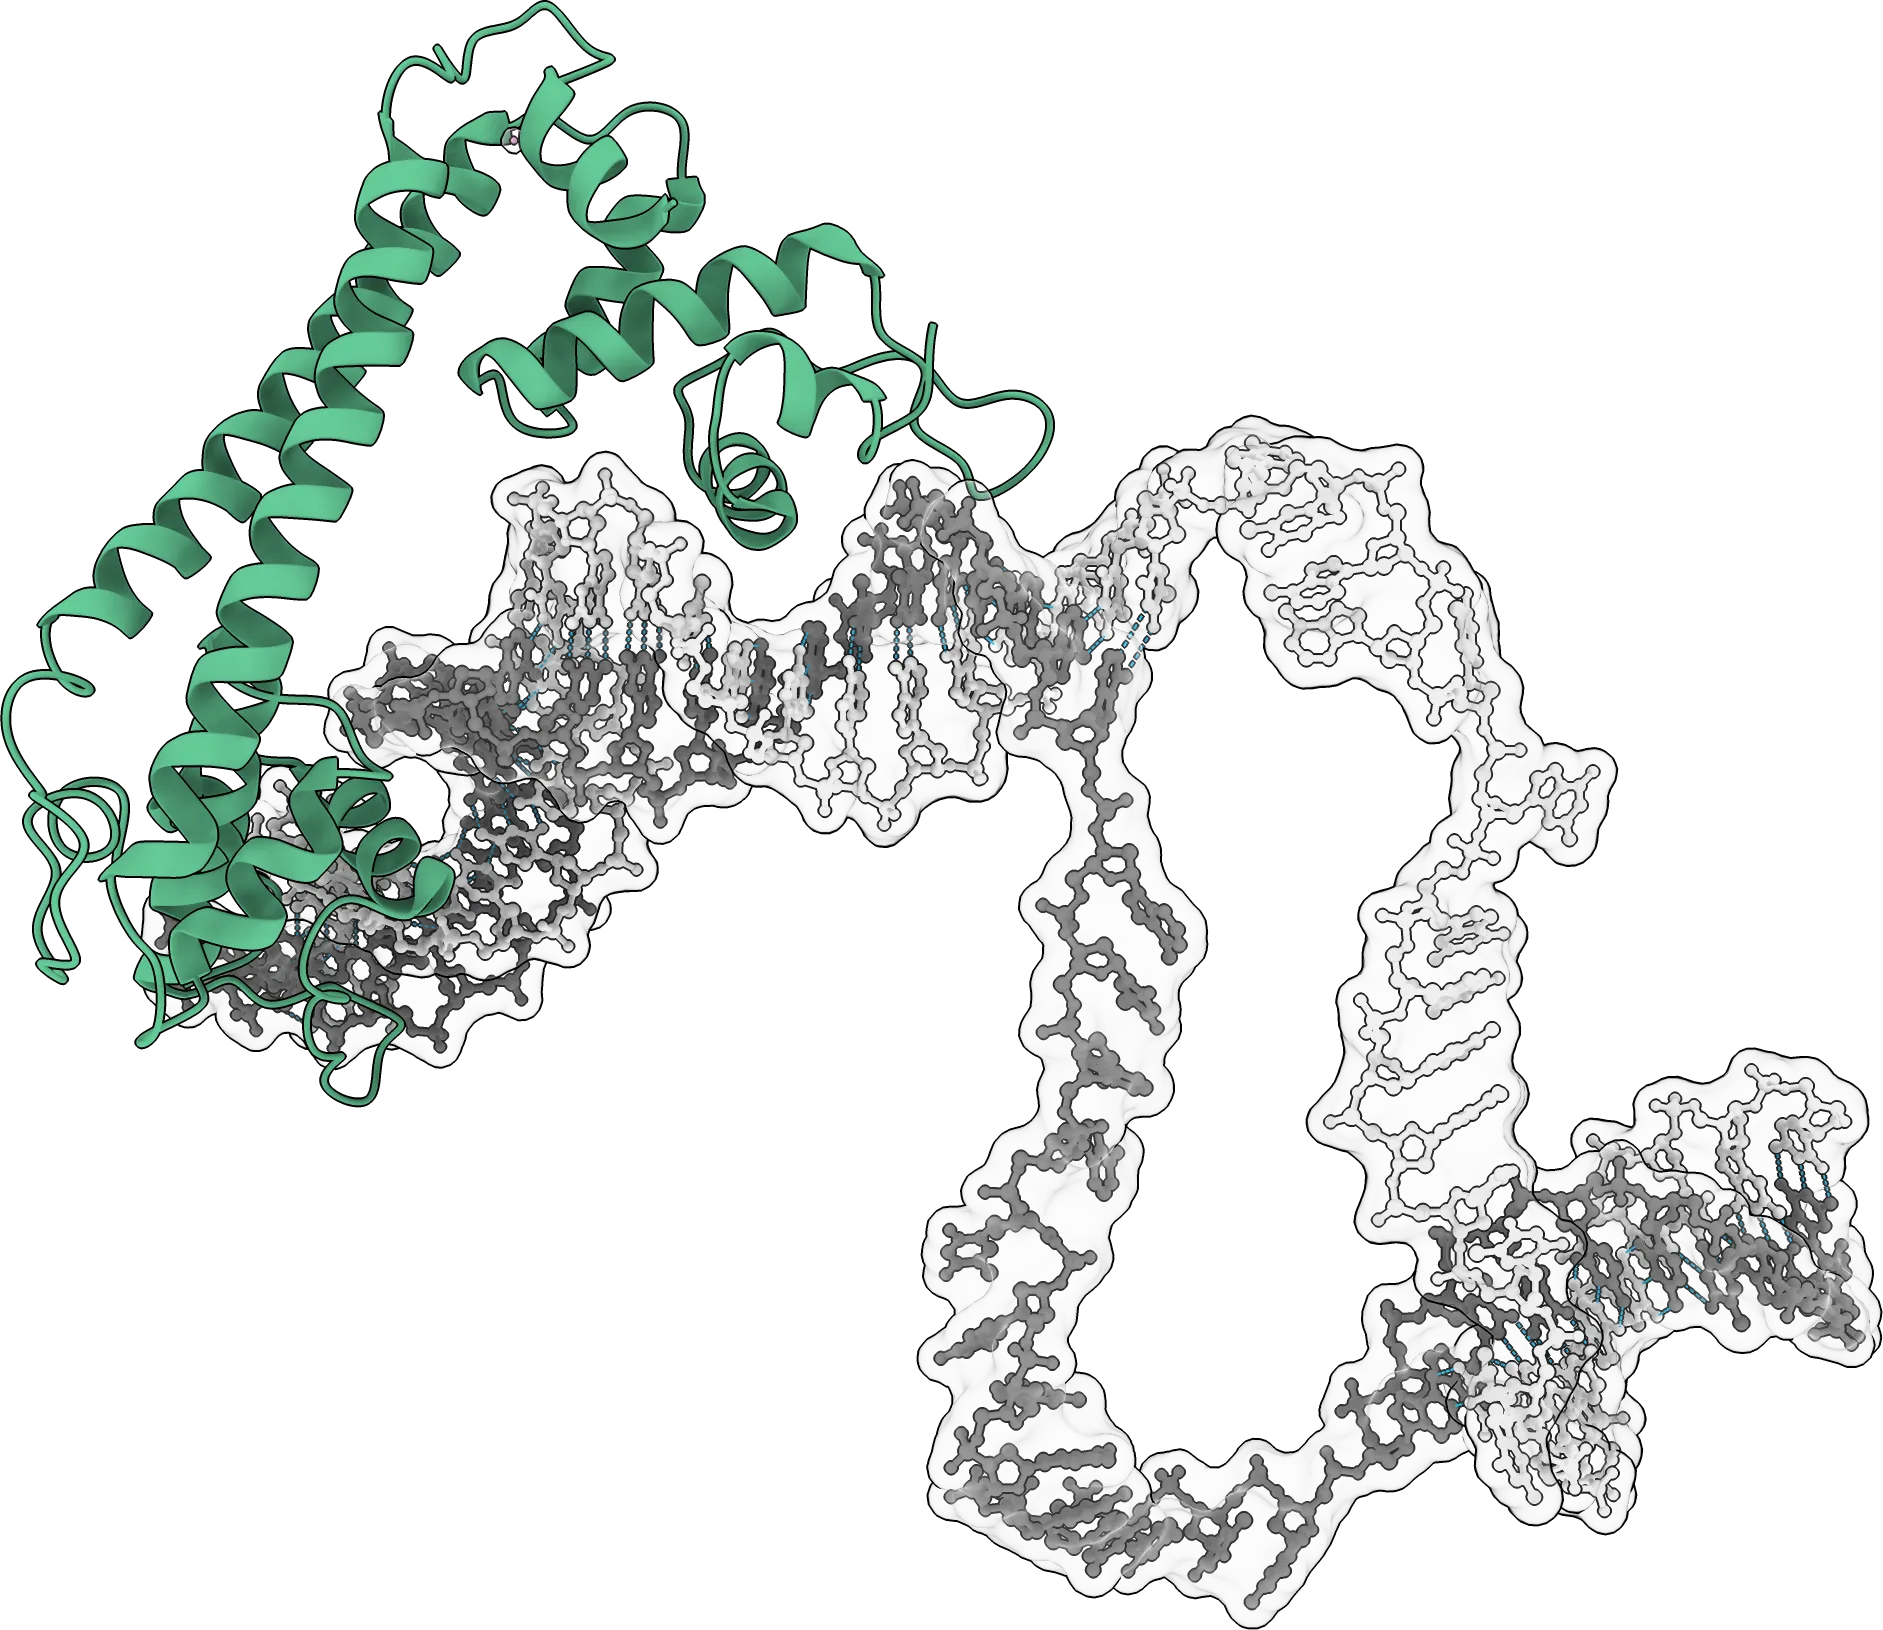
Small regulatory proteins called ligand-inducible transcription factors control how prokaryotes respond to small molecules. Upon binding to their cognate small molecule, these proteins induce the transcription of specific genes. Most famously, a select few, including TetR, LacI, and AraC, are widely used in gene expression systems, while others, such as EthR and MtrR, contribute to broad-spectrum resistance in the deadly pathogens M. tuberculosis and N. gonorrhoeae. Despite having sequenced >10 million of these proteins across prokaryotic genomes, we understand the function of less than 1%.
We aim to map the complete repertoire of small molecule effectors and regulatory targets for this class of proteins. Doing so would help us predict how prokaryotes respond to chemistry, guiding the development of new treatments for microbial infections and improved strains for chemical fermentation.
Towards this goal, we have created the first database of prokaryotic transcription factors with literature-referenced chemical and DNA interactions (groovDB) and are expanding it via collaborations. We have also developed computational tools to predict DNA specificity (Snowprint) and ligand interactions (Ligify) from protein sequence. By augmenting these tools with literature-mining LLMs and massively parallel experimentation, we aim to chart a chemogenetic atlas of all prokaryotic organisms.
Building an oracle for small molecule biosensors
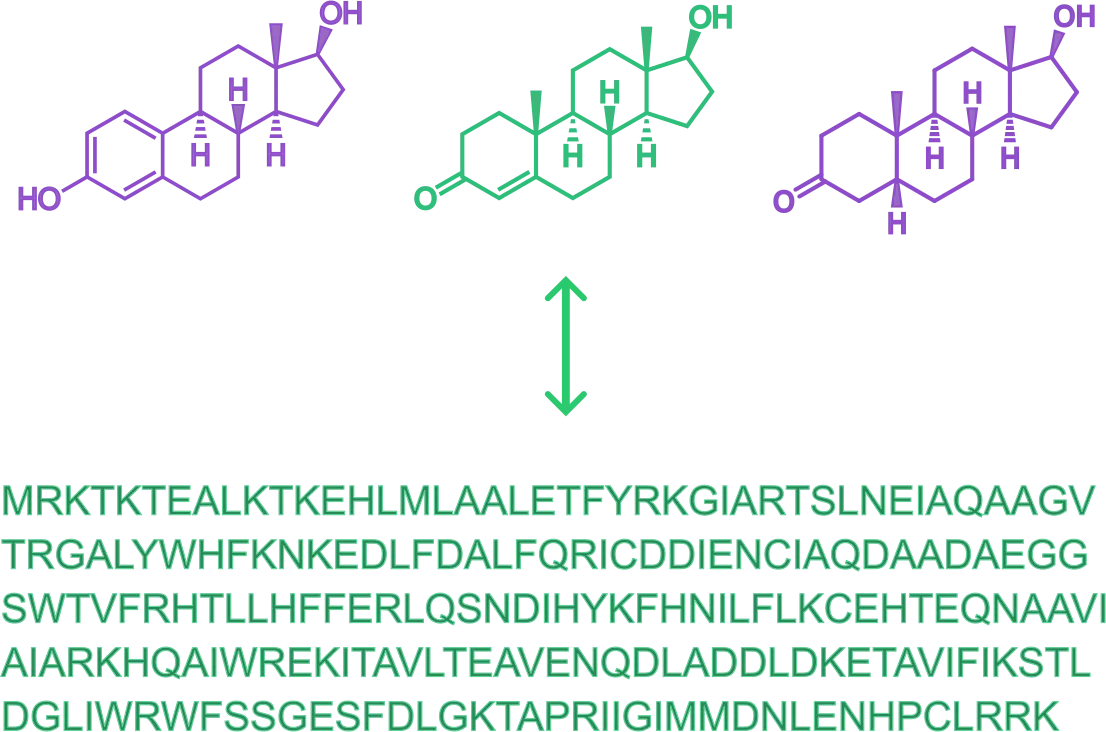
A Holy Grail for bioengineers is the ability to generate protein biosensors at will for user-defined chemical signatures. In other words: input chemical specification, output protein sequence. Unlocking this capacity would not only contribute to our understanding of how chemical specificity is encoded in proteins, but also empower applications in medical diagnostics, metabolic engineering, and synthetic biology.
The workhorses of our campaign are a particular class of bacterial regulatory protein called multidrug regulators. We consider them the stem cells of biosensors in that they promiscuously bind structurally diverse molecules, yet only a few mutations are needed to convert them into extremely high-specificity binders. Through massively parallel experimentation, large chemical library screening, and computational model training, we are charting the chemical landscapes that multidrug regulators recognize, and probing how mutations change their specificity profiles. Our datasets are collected in close collaboration with an international network of labs, providing cross-institution data that will serve as the foundation for building chemical-to-biosensor models.
Generative biocatalysis
Engineered enzymes are transforming chemical manufacturing, especially for pharmaceuticals. Yet despite the substantial commercial interest, enzyme engineering is still a process of ‘molecular tinkering’ rather than precision engineering. Even today, companies rely on iterative cycles of semi-random enzyme design with slow chromatographic methods to evaluate enzyme performance. We aim to build large enzyme phenotype datasets and the models necessary to predict enzyme function from sequence, breaking this cycle.
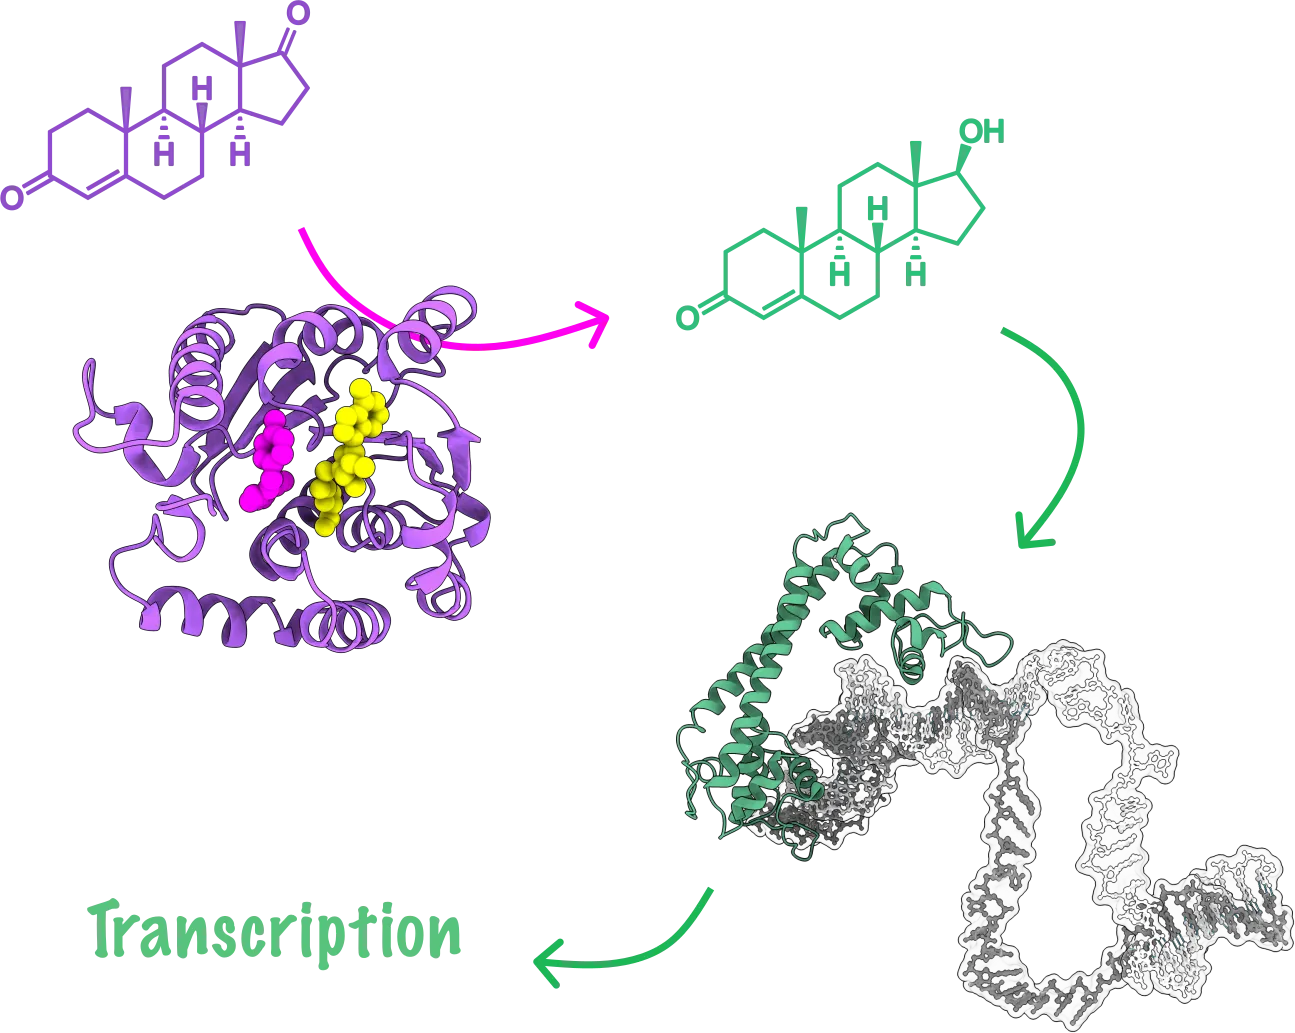
Using custom biosensors as a relay, we can couple enzyme activity and specificity to cell growth via antibiotic marker expression. By barcoding enzyme libraries, these growth-coupled biosensor circuits enable us to read enzyme phenotypes in a pooled format with a massively parallel sequencing readout, scaling to >104 enzymes per experiment. For particularly challenging measurements, like quantifying enantioselectivity that require >30-minute chiral chromatography runs, our methods are >1 thousand times faster than gold-standard assays. The resulting datasets then enable us to train computational models that aim to predict and generate enzyme sequences with targeted functions. We are most interested in phenotypes traditionally difficult to quantify for industrially valuable enzymes, including enantioselectivity and regioselectivity for classes such as imine reductases, ketone reductases, ene reductases, and transaminases.
Measurement innovation
We are constantly thinking of ways to measure harder phenotypes — better, faster, stronger. This includes:
- Multiplexing biosensor arrays to track a wider diversity of molecules per experiment.
- Developing in vitro assays to better scale protein and chemical diversity beyond what is offered in vivo, while also mitigating cellular toxicity and membrane permeability effects.
- Inventing biosensor-enabled methods for resolving enzyme kinetics at scale.
Join our team
We are always looking for passionate and curious people to work with! Currently, we are actively recruiting postdocs, staff scientists, technicians and graduate students. If you would like to collaborate or become a member of the group, please contact Simon by email.